Why Traditional Web Hosting Is Dying and What Smart Site Owners Are Moving To Instead
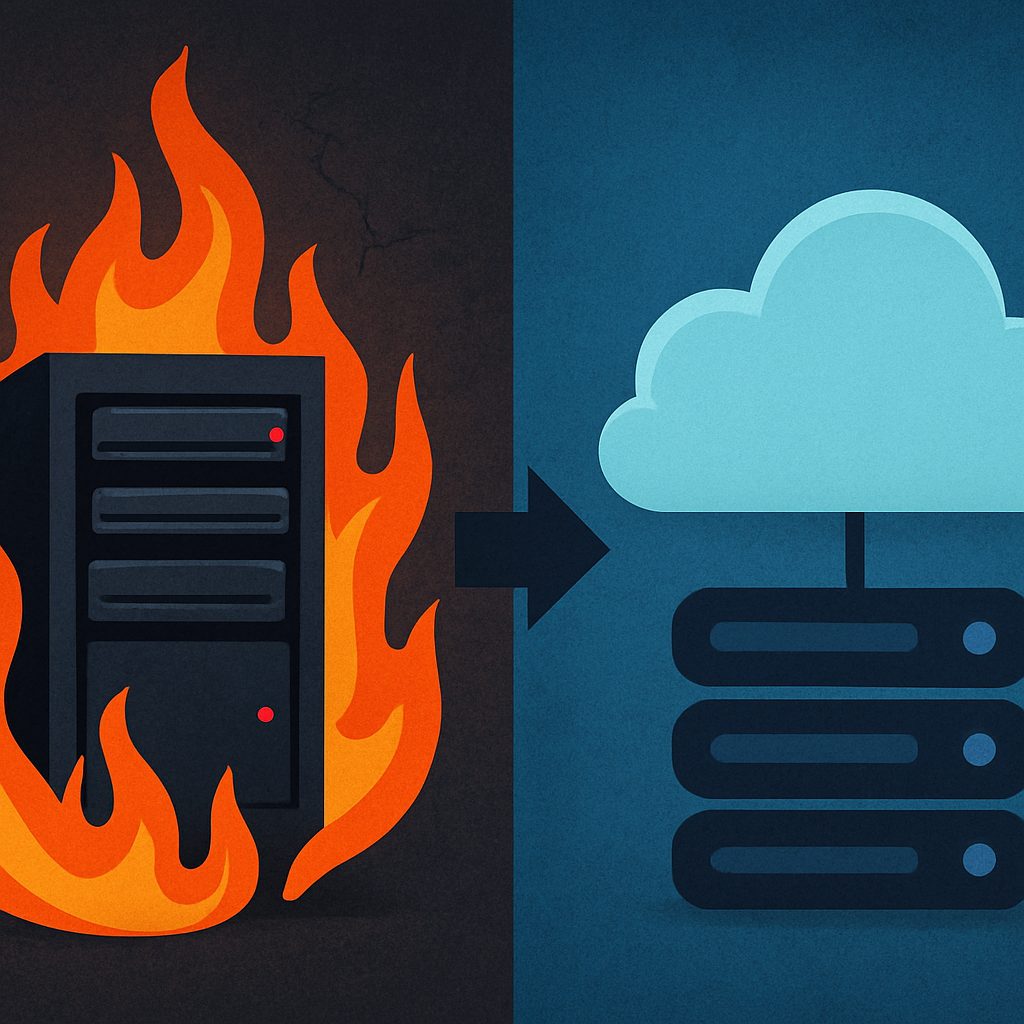
Traditional web hosting no longer keeps pace with a global audience that expects instant, personalized experiences. The future of web hosting serverless edge computing is redefining how sites perform by moving compute to the network edge for lower latency, automatic scaling, and stronger resilience. This post breaks down the data, profiles practical platforms, and provides a concrete migration playbook so you can evaluate options, forecast costs, and plan a safe, measurable transition.
The Decline of Traditional Web Hosting and What It Means for Your Site
Traditional web hosting centralized compute is hitting latency ceilings as global audiences demand instant experiences. When requests travel from distant corners of the world to a few core machines, TTFB and interactive delays creep in, and even a fast CDN can’t fix every path. The business impact is real: lower engagement, higher bounce, and reduced conversions on the pages that matter most. This is not a theoretical problem; it’s a direct lever on user experience and revenue.
Cost, scalability, and operational complexity of traditional hosting in 2026 continue to scale with traffic and features. Scale typically means bigger machines, more licensing, and heavier maintenance burdens—from patching to backups to disaster recovery testing. When regional spikes hit, you overprovision in some zones and underprovision in others, while your ops team wrestles with configuration drift across environments.
Security and governance pressures on legacy setups grow as data flows stretch across borders and edge-like needs emerge. Centralized hosting concentrates risk—one breach can expose many users—and regulatory requirements force strict data residency decisions that are hard to enforce with a single region. Disaster recovery remains slow if you can’t fail over globally without user-visible downtime. You need complex failover plans, cross-region certs, and continuous compliance monitoring.
Business signals that point toward edge and serverless are hard to ignore. Cloud providers are expanding edge footprints, and developers expect to deploy code at geographic proximity to users for fast, personalized experiences. That shift puts edge-first patterns on the roadmap: static frontend on CDNs, dynamic APIs behind edge functions, and data processing at the edge to reduce central load. See edge computing resources from Cloudflare, Netlify, Vercel, AWS and Fastly for options: Cloudflare edge computing, Netlify Edge Functions, Vercel Edge Functions, AWS Lambda@Edge, and Fastly Compute@Edge.
Concrete Example: A midsize online retailer with US, EU, and APAC traffic kept checkout on a centralized host while marketing pages ran through a CDN. European users faced noticeable checkout latency during campaigns, hurting conversions. After moving authentication and region-aware inventory lookups to edge functions deployed near EU and APAC nodes, login times improved for regional visitors and cart updates stayed responsive during peak promotions, without rearchitecting the core backend.
- Trade-off: Governance and data residency become multi-region and multi-runtime complexity.
- Trade-off: Tooling and monitoring get fragmented across platforms.
- Trade-off: Potential vendor lock-in and migration friction.
- Trade-off: Incremental cost curves can complicate budgeting.
Next steps: map latency-sensitive paths, select two complementary edge platforms aligned with your stack, and plan a 6–12 week pilot with rollback options and a clear success metric.
Serverless Edge Computing Demystified: Principles, Pros, and Practical Impacts
Principles of serverless edge computing are not theoretical: compute moves to geographic proximity, it relies on event-driven runtimes, and it scales automatically. This is central to the future of web hosting serverless edge computing: push logic to the edge, run lightweight functions, and compose services at the edge to reduce round-trips and keep data near users.
- Latency-centric design: Compute moves to regional edge nodes, slashing TTFB and improving interactivity for globally distributed audiences.
- Elastic edge scaling: Capacity ramps on demand without long-lived reservations, reducing over-provisioning.
- Security and governance at the edge: Edge expands the attack surface; requires strong identity, encryption, and governance policies.
- Developer velocity: Ship features faster by deploying small functions at the edge instead of waiting for backend changes.
- Authentication and session management at the edge to verify tokens and personalize without round-trips to origin.
- Personalization and feature flags delivered by edge logic that runs near users.
- Image optimization and content adaptation on the edge to reduce payload and speed up rendering.
- Dynamic content routing and API composition enabling lightweight services to orchestrate responses near the user.
Concrete Example: A mid-sized ecommerce site uses edge compute to validate session tokens and steer users to personalized experiences at the edge, while static assets are served from a CDN. In a four-week pilot across US and EU regions, the site measured a TTFB improvement in the 25–40 ms range and a noticeable uplift in add-to-cart speed during peak hours.
Edge introduces real trade-offs: debugging across distributed runtimes is harder, cold starts vary by vendor, and there are data residency and compliance considerations. Costs can become volatile if you misestimate per-request and data transfer, and vendor lock-in remains a real risk if you lean too hard on a single runtime. Plan for governance, clear ownership, and ongoing cost controls from day one.
Takeaway: start with a minimal, measurable edge-first pilot focused on latency improvements and content personalization, then expand regionally and across APIs.
A Practical Landscape: Tools and Platforms Shaping the Edge Era
Edge-era tooling isn't a single toolchain; it's a pragmatic ecosystem. For site owners, the practical move is to assemble a stack that puts compute wherever it matters: static assets on the edge, lightweight dynamic logic also at the edge, and heavier data processing behind a familiar cloud gateway. The goal isn't a wholesale replacement of hosting; it's reducing latency where it hurts and keeping governance and cost in check. In practice that means an edge-first baseline plus selective platform strengths layered in as traffic patterns demand them.
Platform profiles at a glance
Each platform specializes in a slice of the edge workflow, and your choice should map to how your site earns or loses performance. Below are the primary profiles you’ll encounter in practical deployments.
- Cloudflare Workers and Edge compute capabilities: global reach, lightweight edge logic, routing, image optimization, and per-request pricing that rewards steady, near-zero latency operations.
- AWS Lambda@Edge and CloudFront integration: strong if you already operate in the AWS ecosystem and want API proximity without rewriting large portions of backend services.
- Netlify Edge Functions: frontend-first deployments integrated with Netlify hosting; simple, fast setup for sites that rely on Netlify for CI/CD and static-to-dynamic handoffs.
- Vercel Edge Functions: optimized for Next.js and modern frontend apps; ideal for SSR-at-the-edge and automatic routing decisions that align with frontend-driven UX.
- Fastly Compute@Edge: high-throughput, real-time workloads; excels at personalized content, streaming, and security-centric edge processing.
Choosing a platform isn’t about chasing the latest buzzword. It’s about aligning the stack to your traffic profile, data needs, and team capabilities. If most of your value is in the frontend experience and quick dynamic personalization, a frontend-first combination (Netlify or Vercel at the edge) can be enough. If you run a global storefront with complex rules and compliance constraints, a mixed approach that combines a capable edge layer with your existing cloud region strategy often pays off.
Platform selection should be guided by a few concrete criteria: regional presence and network topology, data residency and governance requirements, ecosystem and tooling support, ease of developer onboarding, and total cost of ownership. In practice, you’ll often see teams pair a lightweight edge runtime for the front end with a more robust API layer hosted where data sovereignty and compliance demand control.
Concrete use-case: a mid-market retailer deploys Cloudflare Workers for edge routing and basic personalization, Netlify Edge Functions for the frontend, and AWS for the core inventory API. The result is a measurable drop in TTFB across top markets (roughly 90–120 ms in key regions) and a smoother checkout experience, without ripping apart their existing backend. This pattern keeps latency predictable while preserving governance over sensitive data in familiar regions.
Be mindful of the tradeoffs: edge platforms introduce more moving parts, which can complicate debugging and observability. Mixing platforms increases coordination and staffing requirements, and data egress or stringent data-residency rules can erode the simplicity you hoped edge-first would deliver. If your team is not prepared for multi-vendor orchestration, you’ll pay in operational overhead and slower iteration cycles.
End-to-end success comes from a staged approach: start with a minimal edge-enabled project, validate latency and cost, then layer in additional platforms as needed. A simple pilot that combines frontend edge hosting with a single edge function tier is enough to expose early bottlenecks and governance gaps before you scale.
Migration Playbook: From Traditional Hosting to Edge First
Migration to edge-first isn't a single switch – it’s a design and governance project that starts with mapping latency-sensitive paths and defining rollback criteria. If you treat it like a hardware upgrade, you’ll miss the real work: data flows, authentication boundaries, and how you validate performance under real user conditions. A disciplined plan yields predictable outcomes, not surprises when traffic spikes.
Before you design, ground decisions in observed performance and governance realities. Review platform profiles and benchmarks to avoid hype and vendor lock-in, and use internal references such as BestWebHosting4You to anchor a reality check.
Assess your current architecture and identify latency-critical paths. Catalog pages and APIs that most influence user-perceived speed, map data flows, note third-party integrations, and audit existing caching rules and origin configurations. This discovery provides the migration lane lines you will map against toward an edge-first target.
Define an edge-first target architecture: static frontend on the edge, dynamic APIs behind edge functions, and a lean identity layer that can authenticate at the edge without a trip to the origin. Plan a robust caching strategy with clear cache-control headers and a fall-back to origin for stale content. Design for idempotent operations and predictable data consistency to avoid edge-induced surprises.
- Inventory latency-critical components and user journeys across desktop and mobile.
- Designate a pilot scope that minimizes risk while proving core gains.
- Draft a phased rollout with explicit rollback criteria and rollback tests.
- Define security, data governance, and residency requirements at the edge.
- Set up observability: metrics, traces, and alerts tuned to edge latency and cache health.
Concrete example: A mid-size retailer with a global audience ran a pilot by moving the homepage and product listing pages to edge-first hosting, while keeping the checkout API behind edge functions. They observed 40-60 ms reductions in TTFB for EU and APAC users and a 70% drop in origin requests during peak times; the rollout required adding a session-aware cache and ensuring consistent authentication across edge nodes.
Trade-offs matter. A multi-vendor edge strategy adds resilience but increases governance overhead and compatibility risk. You’ll need clear APIs, portable runtimes where possible, and centralized security controls to prevent drift. Data residency and compliance should be baked into the plan from day one to avoid costly rework later.
Monitoring and observability at the edge demand discipline. Instrument edge functions with granular metrics, maintain end-to-end tracing across edge and origin, and set performance budgets to prevent regression. Regular post-mortems on incident data help refine routing rules and cache strategies without harming user experience.
Takeaway: plan a 6–12 week pilot with explicit rollback criteria and cost guardrails, then scale in measured increments aligned to traffic patterns and business outcomes.
Cost and Value: Building a Realistic Case for Edge
Edge computing is not a free upgrade. The value sits in total cost of ownership and business impact, not just a monthly price. Pricing models vary widely across platforms – per request, per function, data transfer, storage, and tiered bandwidth – so a realistic forecast requires scenario planning and governance. When you add base hosting, CDN, security, backups, incident response, and the operations time to manage a distributed stack, the headline price can swing significantly. The real question is not whether edge is cheaper, but whether the spend translates into tangible performance gains that move business metrics.
A practical framework starts with mapping where users actually experience latency and where dynamic logic lives. Put static frontend on the edge and keep dynamic API calls behind edge functions. That separation makes cost modeling tractable and helps you test performance and reliability early. Be mindful of cold starts at the edge and the extra data transit when payloads cross regions; plan around warm caches and predictable eviction.
Example: a mid-sized content site with 60,000 monthly visitors and 1.2 million page views per month. Under traditional hosting plus CDN, the all-in cost runs around 500 per month, including hosting, security, and backups. An edge-first approach – static assets delivered from the edge, with a handful of edge functions for authentication and personalization, and modest data egress – costs around 180 per month. If caching reduces origin fetches by roughly 60 percent, you effectively cut the origin burden by another sizable margin, bringing total monthly cost closer to 120 to 150. The result is not just a lower bill; it is a faster site that converts more pages and retains visitors longer. In tests, sites that optimize for edge delivery see improvements in LCP and conversion that can compound over time.
Two critical trade-offs: edge is not a silver bullet for all workloads. If your workloads involve heavy continuous data processing at the edge, costs can rise. Data residency and governance require a plan; multi-vendor complexity increases; you will need robust observability across edge and origin to avoid drift between what you deploy and what users experience.
Budgeting for edge-first adoption is as important as the architecture itself. Use a disciplined process to forecast, monitor, and adjust as traffic patterns evolve. A practical approach includes mapping latency-sensitive paths, building scenario-based forecasts, running a controlled pilot, and establishing governance that ties cost to measurable outcomes.
Important: edge pricing is not a single price tag. It varies by region, plan, and usage. Run multiple scenarios and keep a tight link between cost deltas and performance gains.
Takeaway: start with a conservative edge pilot, measure business impact, and scale only when the ROI is clear and governance is in place.
Putting It Into Practice: A Practical Roadmap for 2026
Edge-first is no longer optional for site owners who care about speed, reliability, and cost. This is a practical, grounded roadmap for 2026—focus on bounded pilots, measurable milestones, and governance before scale.
Treat the move as a program, not a single swap. You’ll split work into phases, lock in guardrails for data and security, and measure every milestone against tangible business impact—load time, conversions, and uptime budgets.
- Phase 1 — Audit latency-critical surfaces: Map the top pages and APIs, measure TTFB across regions, and catalog assets that must stay in sync with origin.
- Phase 2 — Prototype a minimal edge project: Launch a marketing site with dynamic elements (localization, promo banners) served via edge functions to prove latency and stability.
- Phase 3 — Design for incremental rollout: Plan staged deployments by geography and feature, with clear rollback points and metrics for each stage.
- Phase 4 — Governance and cost controls: Establish data residency rules, logging, access controls, and alerts on edge usage and egress.
- Phase 5 — Monitoring and optimization: Instrument end-to-end latency, cache efficiency, and error budgets; set a cadence for quarterly optimization cycles.
Concrete use-case: a mid-market retailer runs a global marketing site with localized content and a promo banner that personalizes offers by region. The pilot moves the homepage and product pages to edge-hosted assets, runs a lightweight edge function for regional pricing hints, and keeps checkout APIs behind the origin. In a 6-week window, this setup reduces TTFB by roughly 30–40% in target regions and improves first-meaningful paint without touching the checkout flow.
Two practical patterns teams actually deploy: Pattern A combines frontend hosting on Netlify or Vercel with Edge Compute on Cloudflare Workers and a centralized API backend on AWS API Gateway and Lambda. Pattern B leans toward a more integrated stack—Cloudflare Pages with Compute@Edge for both frontend and edge logic, plus a scalable origin API on a managed serverless backend. Each pattern trades governance complexity against ecosystem maturity and cost predictability; pick the mix that aligns with your stack and data needs.
Security, data governance, and compliance are real constraints at the edge. Expect new data residency questions, expanded attack surfaces, and stricter logging requirements. Build a simple, portable policy for what runs at the edge, who can modify it, and how you audit it before you scale.
Cost literacy at the edge matters: pricing models vary widely (per-request, per-function, data transfer, and cache misses). Create a forecast that treats edge as a variable, not a fixed line item—then bake in caching strategies and region-aware routing to keep costs in check.
Start with a bounded, strategic pilot and lock in a governance model before scale. The six-to-eight-week window is enough to prove ROI and learn what to migrate next. Next step: initiate a six-to-eight-week pilot focused on a high-visibility page and a small set of edge features.